# Build agents with Integrail.ai
Welcome to Integrail, the #1 AI Multi-Agents design and deployment platform that requires no coding. We're thrilled to have you here! Whether you're a seasoned professional or just starting out, Integrail is designed to make your journey with AI Multi-Agents smooth and enjoyable.
Integrail empowers you to design, deploy, and manage advanced AI agents that automate tasks, perform searches, and handle complex workflows. These AI agents can be built through an intuitive no-code interface. Here’s how Integrail’s agents work:
**AI Agents:** Build and deploy custom AI agents that can perform tasks like responding to customer inquiries, generating content, and managing data. These agents can tap into knowledge bases synced with live data from sources like Google Drive, Slack, and your CRM to answer queries or handle workflows.
**Smart Search Agents:** Consolidate your data across various platforms (Google Drive, OneDrive, Slack, etc.) and enable your AI agents to conduct semantic searches, retrieving relevant information from multiple sources in real time.
**Automation Agents:** Automate repetitive tasks by setting agents to run workflows triggered by specific events (e.g., an email or Slack message). Integrail agents can autonomously take actions such as sending follow-up emails, updating databases, or creating new documents in tools like Notion or Airtable.
**Content Generation Agents:** Leverage Integrail agents to create personalized content at scale, from marketing emails to detailed proposals, tailored call summaries, and even visual content. These agents follow predefined formats and styles to maintain consistency across all outputs.
**Workflow Orchestration:** Break down complex processes into smaller, manageable sub-tasks that are handled by specialized agents. Each agent is assigned a role, mimicking human decision-making across various steps in the workflow.
***
### Dashboard
The **Integrail platform's core** is the agent-based workflow, known as an AI pipeline. To create a new workflow, go to the "Agents" section and click "New Agent" at the top left to start building a new AI flow that automates your tasks and processes.
***
### Integrations
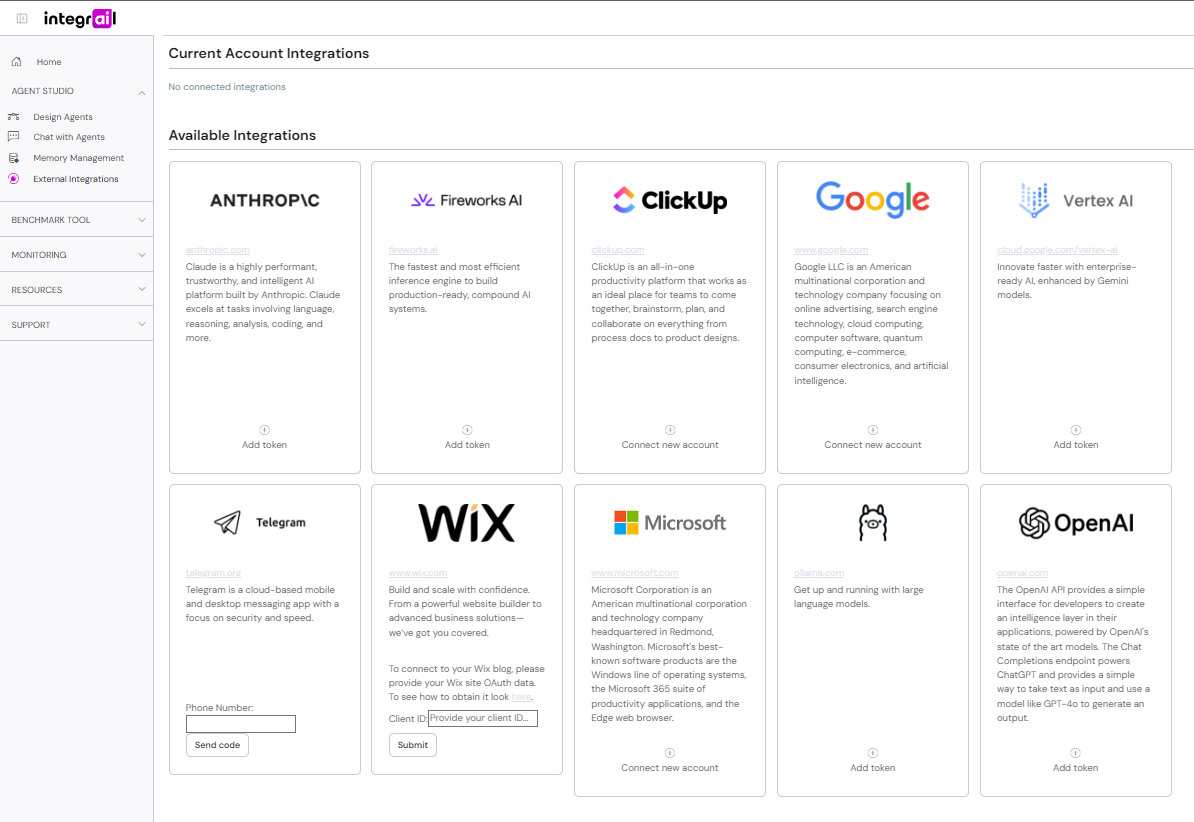
Integrail agents can seamlessly integrate with popular platforms such as **OpenAI, Anthropic, OLLAMA, Google Vertex, Fireworks, Google, Microsoft, Telegram, ClickUp, and WIX** to automate workflows, manage data, and enhance productivity across your existing tools and services.
***
We’d love to hear from you! Reach out to ****
# Quickstart
#### Getting Started Tutorial
Ready to dive in? Let's get you set up and on your way to creating powerful AI Multi-Agents for your business needs.
**What is an AI Multi-Agent?**\
An AI Multi-Agent is an agent that can interact with humans and external software systems, understand vague tasks, and perform them for you. For example, an agent can help you build your marketing strategy, or create a draft email based on your sales pipeline status. These agents are much more powerful than basic chatbots like ChatGPT.
***
{% embed url="" %}
#### Step 1: Create an Account
First things first, you'll need an account.
1. Go to our signup page to create an account.
2. If you already have an account, log in here.
***
#### Step 2: Create a Basic AI Agent
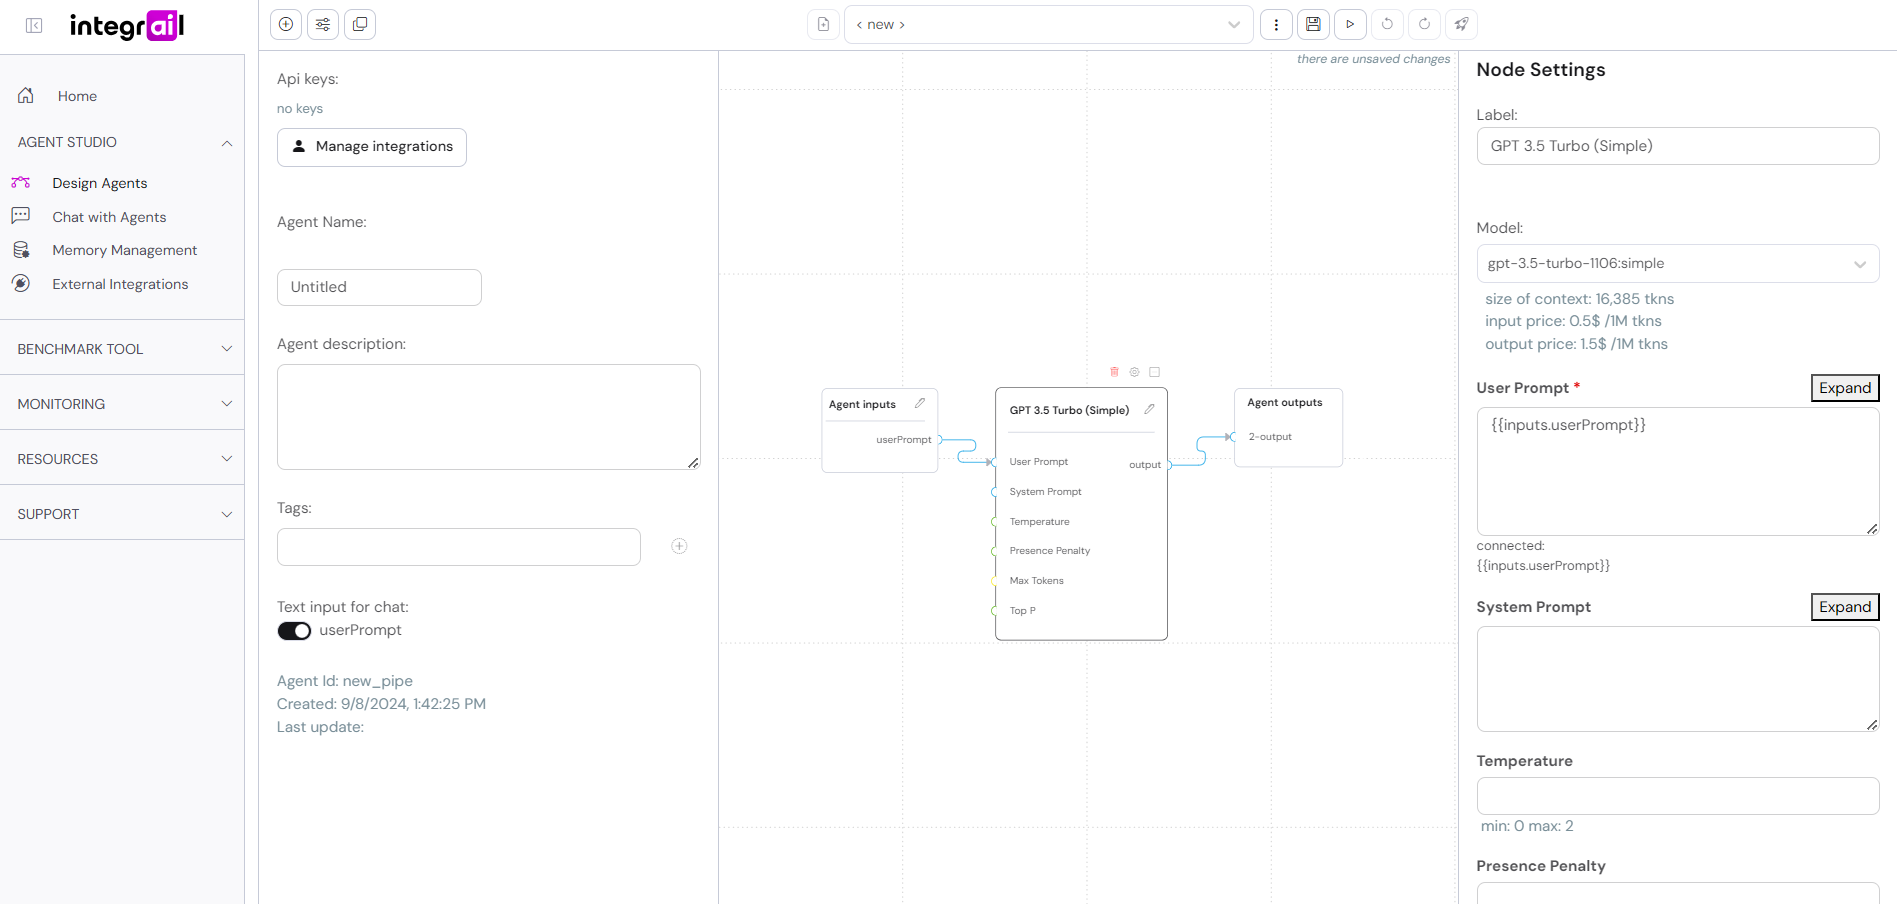
1. Go to **Agent Studio** from the left-hand menu.
2. Click the **New Agent** button in the top menu to create a new agent.
3. You'll see the agent's name switch to `< new >`.
4. Name your agent.
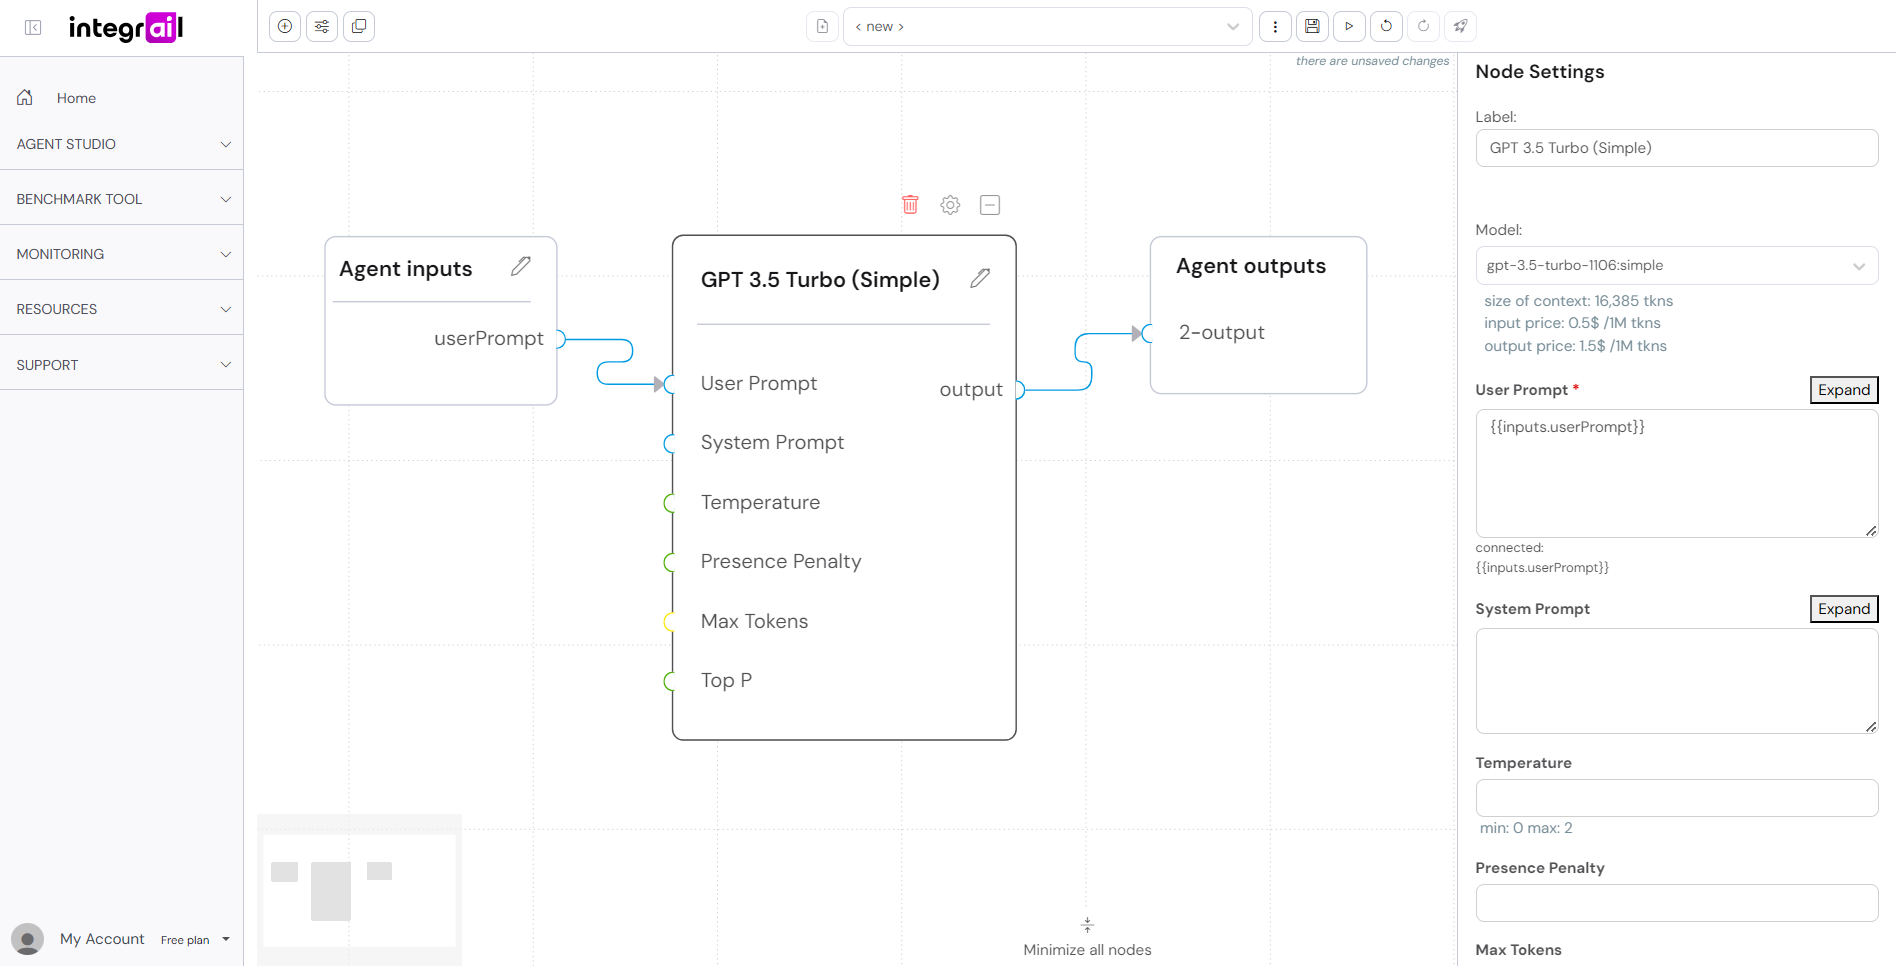
**Checkpoint:** You have successfully created a basic agent consisting of Inputs, an "LLM" (Large Language Model) node, and Outputs—all connected. This is the simplest possible AI agent.
***
#### Step 3: Customize Your Agent's Parameters
1. Click on the **"LLM Simple"** node on the canvas.
2. Adjust the following parameters:
* **Label**: Rename the box for easier identification.
* **User Prompt**: Input your action request here.
* **Model**: Choose from various LLMs (Large Language Models) depending on your needs, such as cost, performance, and context capacity.
* **System Prompt**: Instructs the LLM how to handle user input. For example, you can change the tone of the agent or provide a specific response format like JSON.
**System Prompt Example:**
Create a poetic agent with a sarcastic tone:
```css
"You are a poet with a gentle soul, but life has scarred you. You use sarcasm as your default communication mode. Answer any user's requests or remarks using poetry, rhyme your answers as much as possible, and make them both sarcastic and sad."
```
4. Click **"Agent Input"**, enter something in the User Prompt field, and press the **"Run"** button.
5. Your agent will be saved, and the status of the **"LLM Simple"** box will change to **"Running"**. Wait for it to switch to **"Finished"**.
6. Click on **Agent Outputs** to read the response.
**Checkpoint:** You have now customized your AI agent's parameters.
***
#### Step 4: Compare Your Agent and Base Models
1. Click on **"Run benchmarks"** under the **"Benchmark Tools"** menu on the left.
2. Select models and your agent to compare:
* Top-right: List of popular basic LLM models with indicative costs and context window sizes (the maximum number of tokens a model can handle).
* Your Multi-Agents: List of the agents you’ve created.
3. Enter a prompt like, **"Hi, how are you?"**, and click **"Submit"** to compare the results.
**Checkpoint:** You've successfully tested your agent against basic models. Now, you know which models work best for your needs!
***
#### Step 5: Interact and Deploy
1. Go to **"Chat with Agents"** via the left hand side navigation bar in **"Agents"** menu.
2. Select your agent from the top menu and interact with it as you would with any chatbot.
3. If you want to make changes, return to **Agent Studio**, experiment, and save your changes.
4. Once you're satisfied, deploy your agent to **Integrail Cloud** with a single click (coming soon).
**Bravo!** You've mastered the essentials of AI Agent creation, testing, and optimization. The possibilities are endless!
***
Integrail supports the creation of **Advanced AI Multi-Agents** tailored to your specific business processes. Integrate with external systems like CRM, Email, CMS, and more. Create agents that handle not only text but images, voice, and video.
**Checkpoint:** You are now equipped with the knowledge to build powerful AI Multi-Agents. Keep exploring, innovating, and pushing the boundaries of what's possible with Integrail.
***
We’d love to hear from you! Reach out to ****
# Design Agents
### Build Agents
In the **Agents Studio**, this is where you build and design agents using interconnected nodes. Each node represents a specific function, and you can configure its settings, such as prompts and behaviors, to tailor how the agent interacts. By connecting multiple nodes, you can create complex workflows for your agents, making them perform a wide range of tasks.
***
### Chat with Agents
In the **Chat with Agents** interface, this is where you communicate with your agents directly. You can interact with them by sending queries and seeing their responses in real time. This area allows you to test how your agents react to different inputs and observe their behavior or responses, making it easy to evaluate and refine their performance.
***
We’d love to hear from you! Reach out to ****
# Export/Import agents to JSON
How to export and import Integrail Agents configuration using JSON test files.
Integrail agent configuration can be exported to a JSON file.
This JSON file can be imported as a new agent or overwrite an existing saved agent, even on a different account, so it's a perfect way to backup your Agent building steps or to share your result.
**Be careful when overwriting existing agent configuration. Importing JSON file will replace already saved agent in this slot.**
#### How to export an agent to JSON file.
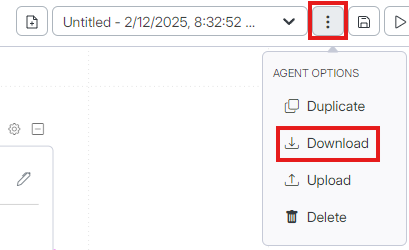
1\) Click on three vertical dots to the right of agent selector:
2\) Click the "Download" option.
3\) The browser will receive a JSON file and download it.
#### How to import an agent from a JSON file.
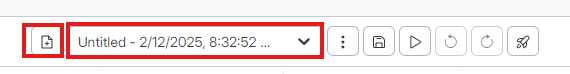
1\) Select the agent you want to overwrite in agent selector (dropdown), or make a new agent by pressing the icon to the left of the agent selector, that looks like a page with a "+" sign:
2\) Click on three vertical dots to the right of agent selector:
3\) Click the "Upload" option, browse to your file and select "Open".
This will overwrite the agent with the saved confguration.
**Be careful when overwriting existing agent configuration. Importing JSON file will replace already saved agent in this slot.**
# Misc
### My Agents
The "My Agent" node enables you to include another agent within a larger agent workflow, creating modular, reusable systems. The key concept here is encapsulation, where the embedded agent runs independently from the main agent's processes.
This separation ensures that the embedded agent handles its own tasks, logic, and operations without interfering with the flow or state of the broader agent. The outer agent simply interacts with the results, making complex, multi-agent systems manageable and efficient.
### Read CSV
This node accepts input in a form of CSV file. You can specify what delimeter to use.\
It outputs an array of lines from the CSV file, organized in a dictionary, in JSON syntax.
To pass a file as an input, you must use a "file" type agent input, and upload the CSV file.
### Serialize JSON
Serialize and object (such as Google Search output) and return a JSON string.
### Parse JSON
Parse a JSON string and return a list of strings for each element.
# LLM
### Caller 2
The **Caller 2** node is designed to handle commands and responses based on both user and system prompts. Below is a breakdown of its key parameters:
* **Label**: The name given to the node. You can rename this to something meaningful for your workflow.
* **Model**: This allows you to select the language model that will generate responses. You can choose from various models depending on your needs.
* **User Prompt**: This field captures the user’s input (or query) that will be sent to the model for processing. It’s the starting point for generating a dynamic response.
* **System Prompt**: Here, you can set a predefined set of instructions for the model to follow. This can guide the AI on how to behave during the interaction (e.g., responding in a specific tone, or avoiding certain information).
* **Commands**: You can define a list of commands for the node to execute. These commands are triggered based on user inputs or specific conditions within the workflow. Command names must be single words, without spaces.
* **Fallback Outputs**: This field allows you to define a backup or fallback response in case the model call doesn’t return a valid output or fails. It's helpful to maintain flow even in the event of an error.
* **Results**: This section is where the final response generated by the model or command execution is displayed. It's what will be sent back to the user as the output.
This node is typically used when you need to combine user input with system-level commands and provide a response that either calls the model or processes information based on set parameters.
***
### Chart Formatter
The **Chart Formatter** node is designed to convert raw text or uploaded files into a structured data format suitable for chart generation. It leverages a language model to analyze the input and output a JSON object containing `labels` and `datasets`, compatible with common chart libraries.
#### Parameters
* **Label**: The display name of the node. You can rename it to reflect its role in the workflow.
* **Model**: Select the language model (such as GPT-3.5 or GPT-4) used to transform the input into chart-ready JSON. The model interprets the input based on a predefined system prompt.
* **Input**: This is the content to be transformed. You can provide either plain text or a file (CSV, JSON, or TXT).
* CSV files will be automatically parsed into structured objects.
* JSON and TXT files are used as-is after validation.
#### Usage
This node is designed to work **as a preparatory step** before chart rendering. Its output is fully compatible with the **Chart Generator** node, which can take this JSON and create visual representations (e.g., bar, line, pie charts).
***
### Chart Generator
The **Chart Generator** node creates high-quality chart images (PNG or SVG) based on structured JSON input. It supports common chart types like bar, line, pie, and doughnut, and automatically styles the output with colors and labeled legends for clarity.
#### Parameters
* **Label**: The name of the node. You can rename it to describe the specific chart it generates.
* **Chart Data (JSON)**: Required. A JSON string that defines `labels` and `datasets`, matching the structure:
* {"labels": \["Label1", "Label2"], "datasets": \[{"label": "Dataset name", "data": \[100, 200]}]}
* **Chart Type**: Choose between bar, line, pie, or doughnut charts.
* **Format**: Choose whether the output should be in **PNG** or **SVG** format.
* **Make Permanent?**: If enabled, the generated chart image will be stored permanently in your account’s file storage.
#### Usage
This node is typically used **after** a data formatting step, such as the `Chart Formatter` node, which prepares raw input into the expected JSON structure.\
Once valid data is available, the Chart Generator transforms it into a visual chart for reporting, dashboards, or export.
***
### Get Chat History
The **Get Chat History** node is used to retrieve past messages from the conversation history. This node is essential when you need to maintain context or reference previous interactions within a workflow. Here's a breakdown of the key elements:
* **Label**: The name of the node. You can rename this to make it more descriptive based on the specific use case.
* **Limit**: This field determines the number of past messages you want to retrieve. Setting a limit helps to control how many messages are brought back into the current workflow context. The minimum limit is 1, meaning it will retrieve at least one message if available.
* **Messages (object\[])**: This is an output object that contains the retrieved chat history, which can be used by other nodes or functions within the workflow. The output will be in the form of an array of messages.
* **Fallback Outputs**: This field allows you to define an alternative or backup action in case no valid chat history is found or if the retrieval fails. This ensures the workflow can continue even if there's an issue with retrieving the chat history.
* **Results**: The actual output from retrieving the chat history will appear here. It can then be passed to other nodes or used for further processing.
#### Usage
This node is typically used when you need to retrieve past messages to inform future actions or responses. For example, it might be used to maintain conversation context or pull relevant details from earlier in the chat to improve response accuracy.
***
### LLM
The **LLM** node is a streamlined way to interact with a language model (like GPT-3.5) to generate responses based on user input. This node simplifies the configuration process while still offering control over essential parameters. Here’s how each component functions:
* **Label**: The name of the node. By default, it's labeled **LLM**. You can rename it to something more specific based on your workflow.
* **Model**: Choose model from the drop down.
Pricing details for input and output are also provided to help you manage costs based on usage.
* **User Prompt**: This is a required field where you input the user's question or message that the model will process to generate a response.
* **System Prompt**: This optional field allows you to set instructions or guidelines that define how the model should behave while responding. For example, you can instruct the model to respond formally or focus on a specific topic.
* **Temperature**: This parameter controls the randomness or creativity of the model's responses. A higher value (closer to 2) produces more diverse and creative answers, while a lower value (closer to 0) makes the output more deterministic and focused.
* **Presence Penalty**: This setting discourages the model from repeating the same content, ensuring more varied responses. Higher values encourage the model to avoid repetition and generate new content.
* **Max Tokens**: This field sets the maximum number of tokens (words or parts of words) the model can use to generate a response. Limiting this helps control the length of the generated text.
* **Top P**: This is a sampling method that controls how broad the model’s responses can be. A lower value restricts the model to consider only the most likely tokens, while a higher value allows more creative and varied responses.
#### Usage
The **LLM** node is ideal for straightforward text generation where you need quick, efficient interactions without a lot of complex settings. It's a simplified interface that still gives you control over key parameters like temperature, token length, and response variability. This makes it perfect for scenarios where simplicity and speed are more important than fine-tuning.
***
We’d love to hear from you! Reach out to ****
# Embeddings
### Embeddings
Converts input data (like text) into numerical vectors that represent the semantic meaning of the data, enabling downstream AI tasks such as similarity searches or natural language understanding.
Parameters:
**Models**: Specifies the model ID to be used for text generation.
**Input**: Defines the input data that will be processed to generate embeddings. This can include text, images, or other data types that need to be converted into embeddings for further use in AI workflows.
**Fallback Outputs**: Specifies the default output to be returned if the model is unable to generate results based on the input.
See this node in example Agent: Customer service agent
***
### Vector Search
**Input**: Defines the input data that will be processed to generate embeddings. This can include text, images, or other data types that need to be converted into embeddings for further use in AI workflows.
**Limit**: This value controls the maximum number of search results returned.
**Min Relevance Score**: Specifies the minimum similarity score required for a result to be considered relevant and returned. For instance, if set to 0.5, any result scoring below 0.5 is filtered out as less relevant.
Most Vector Search implementations use a similarity measure such as **cosine similarity**. In this method, the angle between two embedding vectors (the query and a candidate result) is measured. A score of **1** means the vectors align perfectly (highly similar), while a score of **0** means they are orthogonal (unrelated):
* **0.3 Score Example:** Suggests only a loose relationship to your query. The content may share a broad theme but lacks direct or strong alignment.
* **0.6 Score Example:** Indicates a more meaningful match, showing noticeable alignment with the query’s intent or context.
**Vector Memory Store**: The storage location where embeddings are saved and retrieved during the search. This is the dataset or vector database that the search queries for relevant information. Read more in Vector Memory Management.
**Fallback Outputs**: Specifies the default output to be returned if the model is unable to generate results based on the input.
***
### Save to Vector Memory
Used to store embeddings (numerical representations of data) into a specified memory set for future searches and retrieval. Here’s an explanation of its parameters:
**Input to Embed**: The data you want to convert into embeddings (such as text or images) and store in the vector memory. This input is transformed into a numerical vector for later use in searches.
**Input Full Text**: A full, unprocessed version of the input data (e.g., the original text). This field ensures that while the embeddings are stored, the raw input is also saved for reference during retrieval or debugging.
**Name of the Memory Set**: Specifies the target memory set where embeddings will be stored. Read more in Vector Memory Management.
**Fallback Outputs**: Defines what the system should return if it fails to process the input or store the data successfully, ensuring the workflow remains operational even if errors occur.
This node is crucial for storing embeddings, enabling effective retrieval during later vector searches.
***
### Save Session
Used to store specific pieces of text with a unique identifier, making it easy to retrieve later. Here’s a breakdown of the parameters:
**Text to Save**: This is the actual content or data you want to save during the session. It could be any information you plan to use or reference later in the workflow.
**Unique Name for this Item**: This serves as a unique identifier or label for the saved text. Each item is stored with its own unique name, ensuring it can be easily retrieved when needed.
These fields allow you to save session data in a structured and retrievable format, supporting the continuity of workflows by preserving key information.
***
### Read Session
The Read Session node retrieves previously saved session data using a unique identifier. Here’s what the parameters represent:
**Item Name**: This specifies the unique name of the item you want to retrieve from the session. It should match the name that was used to save the item in the Save Session node.
**Fallback Outputs**: Defines what the node should return if the requested item cannot be found or if an error occurs, ensuring the workflow can continue without interruptions.
This node allows you to pull specific stored data from a session for further processing or use in your workflow.
***
We’d love to hear from you! Reach out to ****
# Text to Image
The **Text to Image** node allows you to generate images based on text descriptions (prompts) using AI models specifically designed for image generation. Here’s a breakdown of the key settings for this node:
* **Label**: This is the name of the node. You can rename it to reflect the specific task or function you are using it for.
* **Model**: This field lets you choose which AI model to use for generating the image. By default, it may be set to a specific model, but you can select from various available models. For a list of models, you can refer to Resources.
* **Prompt**: This required field is where you input a text description of the image you want to generate. The more detailed and specific the prompt, the more accurate the generated image will be based on your expectations.
* **Size**: This setting defines the dimensions of the generated image. Common options include 1024x1024 (as shown), but other sizes may be available depending on the model.
* **Style**: This parameter allows you to choose the style of the generated image. Options like “natural” (as shown) may be available, or you might select other styles depending on the desired aesthetic.
* **Fallback Outputs**: This field allows you to define a fallback action in case the image generation fails, ensuring the workflow continues smoothly.
This node is useful for converting text descriptions into images for various creative applications, from artwork to visual content for projects.
***
We’d love to hear from you! Reach out to ****
# Image to Text
The **Image to Text** node allows you to process an image and generate a descriptive text based on the contents of that image using AI models designed for visual interpretation. Here’s a breakdown of the key settings:
* **Label**: This is the name of the node, which by default is labeled **Image to Text**. You can rename it based on the specific function you are using it for.
* **Model**: This field specifies the model used for processing images. List of available models in [Resources](/agent-studio/resources). Pricing details are provided for input and output tokens to help you manage costs.
* **Image**: This required field is where you input the image that the model will analyze. You can either enter a file URL or upload an image directly. Supported formats include `.jpg`, `.jpeg`, and `.png`, with a maximum file size of 500 MB.
* **User Prompt**: This is a required field where you can add instructions or contextual information to guide the model's analysis of the image. For example, you can ask the model to generate a descriptive sentence or answer specific questions about the image.
* **System Prompt**: You can include specific guidelines in this field to control how the model behaves or how detailed the output should be when describing the image.
* **Temperature**: This controls the randomness or creativity of the model’s output. A higher temperature value produces more creative results, while a lower value makes the responses more predictable and focused.
* **Presence Penalty**: This parameter discourages the model from repeating the same tokens or information, ensuring a diverse and fresh output. Higher values encourage the generation of new content.
* **Max Tokens**: This setting defines the maximum number of tokens the model can use when describing the image. Limiting the tokens can control the length of the output.
* **Top P**: This controls the diversity of responses by adjusting how much of the probability mass the model considers. Lower values focus on more likely responses, while higher values allow for more varied descriptions.
#### Usage
This node is ideal for tasks where an image needs to be analyzed, and a descriptive text or answer is required based on the image content. This is particularly useful for image captioning, generating insights from visual data, or answering questions about images.
***
We’d love to hear from you! Reach out to ****
# Image to Image
### Image resize
* **Purpose**: This node crops an image to focus on a specific area, removing unwanted sections.
* **Model**: `image-crop`
* **Key Inputs**:
* **Image**: The image to be cropped.
* **Left, Top, Width, Height**: Define the cropping boundaries.
### Erase
* **Purpose**: This node is used to erase or remove specific parts of an image.
* **Model**: `stability-erase`
* **Key Inputs**:
* **Image**: The image where erasing will be applied.
* **Mask**: Specify the part of the image to erase via a mask.
***
### Inpaint
* **Purpose**: This node is used to fill in missing or unwanted parts of an image, often referred to as "inpainting."
* **Model**: `stability-inpaint`
* **Key Inputs**:
* **Image**: The base image to be inpainted.
* **Mask**: An optional mask defining the areas to be inpainted.
* **Prompt**: Instructions for what should replace the masked region.
***
### Outpaint
* **Purpose**: This node extends the image beyond its original borders, commonly referred to as "outpainting."
* **Model**: `stability-outpaint`
* **Key Inputs**:
* **Image**: The original image.
* **Left, Right, Up, Down**: Define how much to extend the image in each direction.
***
### Search and recolor
* **Purpose**: This node searches for specific elements in an image and changes their color.
* **Model**: `stability-search-and-recolor`
* **Key Inputs**:
* **Image**: The base image.
* **Prompt**: Specify the element to recolor.
* **Select Prompt**: Define the new color or pattern.
***
### Search and replace
* **Purpose**: This node allows you to search for specific elements within an image and replace them with new ones.
* **Model**: `stability-search-and-replace`
* **Key Inputs**:
* **Image**: The image where the search-and-replace function will be applied.
* **Search Prompt**: Define what you are searching for in the image.
* **Prompt**: Define what should replace the found element.
***
### Sketch
* **Purpose**: This node turns an image into a sketch or line drawing, emphasizing outlines.
* **Model**: `stability-sketch`
* **Key Inputs**:
* **Image**: The image that will be converted to a sketch.
* **Prompt**: You can guide the style of the sketch through the prompt.
***
### Upscale
* **Purpose**: This node enhances the resolution of an image while preserving its original quality, making it sharper and more detailed.
* **Model**: `stability-conservative-upscale`
* **Key Inputs**:
* **Image**: Upload or link the image you wish to upscale.
* **Prompt**: Optionally, provide instructions or context for further image processing.
***
### Structure
* **Purpose**: This node is used to adjust the structural components of an image, allowing for more intricate modifications.
* **Model**: `stability-structure`
* **Key Inputs**:
* **Image**: Upload or link the image whose structure will be modified.
* **Prompt**: Provide detailed instructions for how to adjust or transform the structure of the image.
***
We’d love to hear from you! Reach out to ****
# Image to Video
### Image to video
The **Stability (Image to Video)** node allows you to transform an image into a video using AI-powered models. This can be useful for creating dynamic animations or video content from static images. Here’s a breakdown of its components:
* **Label**: This is the name of the node, labeled **Stability (Image to video)** by default. You can rename it to reflect the specific function of your workflow.
* **Model**: The model selected is `stability:itv` (Image to Video). This model is used to process the input image and generate a video output.
* **Image**: This required field is where you upload the image that will be transformed into a video. You can either enter a file URL or upload an image directly in formats like `.jpg`, `.jpeg`, or `.png`. The maximum file size is 500 MB. Image dimensions must be 1024x576, 576x1024 or 768x768.
* **Fallback Outputs**: This field is used to define an alternative output in case the video generation process fails, ensuring the workflow continues smoothly.
* **Results**: The generated video output is displayed in this field, which can then be used in subsequent nodes or saved as needed.
#### Usage
This node is perfect for use cases where you need to create videos from static images, like generating animated versions of images or video content for various projects.
***
We’d love to hear from you! Reach out to ****
# 3D
### 3D
The **Stability (3D)** node is part of the **3D** section and is used for generating or processing 3D images using AI models. Here’s a breakdown of its components:
* **Label**: The name of the node, labeled **Stability (3D)** by default. You can rename it based on the specific function you are performing in your workflow.
* **Model**: The model selected is `stability:3d`, which is specifically designed for working with 3D images or producing 3D-like effects.
* **Image**: This is the required field where you upload the image that will be processed. You can either provide a file URL or upload an image directly in formats such as `.jpg`, `.jpeg`, or `.png`, with a maximum file size of 500 MB.
* **Fallback Outputs**: This field allows you to specify an alternative action or output in case the image processing fails, ensuring that the workflow continues.
* **Results**: The generated 3D image or processed output will be shown here and can be used in subsequent nodes or saved as needed.
#### Usage
This node is perfect for use cases where you need to generate 3D models or apply 3D effects to an image. It can be used to create visual content for various creative applications involving 3D assets or visualizations.
***
We’d love to hear from you! Reach out to ****
# Text to Speech
### OpenAI TTS
The **Text to Speech (TTS)** node allows you to convert text into spoken audio using AI-generated voices. Below is a breakdown of the key components:
* **Label**: You can rename it based on your specific use case or workflow.
* **Input**: This required field is where you enter the text that will be converted into speech. The text input can be a sentence, paragraph, or any other text-based content.
* **Voice**: This setting allows you to choose the voice that will be used to speak the text. In this example, the voice option is set to "echo," but you can select from a variety of available voices based on your needs.
* **Format**: This defines the audio format in which the output speech will be generated. The default is set to `.mp3`, but other formats may be available, such as `.wav` or `.ogg`, depending on the model's capabilities.
* **Fallback Outputs**: This field allows you to define an alternative output or action in case the text-to-speech conversion fails, ensuring that your workflow continues.
* **Results**: The generated audio file will appear here once the text is successfully converted to speech. This output can then be used in subsequent nodes or saved as needed.
#### Usage
This node is ideal for applications where you need to convert text into speech, such as generating audio responses, narrations, or voiceovers. It can be particularly useful in chatbots, virtual assistants, or any scenario where text-based input needs to be converted into spoken output.
***
We’d love to hear from you! Reach out to ****
# Speech to Text
### OpenAI Whisper 1
The **Speech to Text (OpenAI Whisper 1)** node allows you to convert audio files into text using AI models designed for audio transcription. Below is a breakdown of its key components:
* **Label**: The name of the node, labeled **OpenAI Whisper 1** by default. You can rename it based on your specific workflow or use case.
* **Audio**: This required field is where you upload the audio file that needs to be transcribed. You can either provide a file URL or upload an audio file directly. Supported formats include `.mp3`, and the maximum file size is 500 MB.
* **Prompt**: This field allows you to provide specific instructions or context for how the transcription should be handled. For example, you can give guidance on certain phrases or terms.
* **Temperature**: This controls the randomness of the transcription output. A higher temperature value (closer to 2) produces more creative and varied outputs, while a lower value (closer to 0) makes the output more predictable and consistent.
* **Fallback Outputs**: This field allows you to specify an alternative output or action in case the transcription fails, ensuring the workflow continues without disruption.
* **Results**: The transcribed text from the audio file will be shown here, which can then be passed to subsequent nodes or used as needed.
#### Usage
This node is ideal for transcribing audio content into text, whether for generating subtitles, transcribing meetings, or converting spoken content into written format. It can be used in workflows that involve voice data or audio files that need to be converted into text for further processing.
***
We’d love to hear from you! Reach out to ****
# Web
Web Automation Nodes
### Browser
The **Browser** node in the Integrail flow builder allows users to automate tasks that involve browsing web pages. This node can perform a variety of actions within a web browser, making it a versatile tool for extracting information or automating web-based tasks.
The browser node can be used multiple time over the agent execution, and preserves the same browser session. So you can utilize findVisibleElements, pass them to LLM mode such as ChatGTP, and then use another Browser node down the execution path to continue working with the page.
* **Browser Program**: This field defines the actions the node will execute in the browser. Users can input scripts or commands to control browsing behavior.\
\
The browser program is read by a simple JavaScript parser, so you can use variables and basic loops and conditional functions (for, while, if).\
\
During he process of writing of the program, you can use // to comment out specific lines if needed for testing.
* **Outputs**:
* **content**: The last executed command/variable output.
* **firstScreenshot**: A screenshot of the page at the start of the browsing session.
* **screenshots**: Captures multiple screenshots during browsing.
* **next**: Used for paginated browsing or continuous actions.
This node is ideal for automating data retrieval, capturing visual information from websites, and performing automated interactions with web pages.
#### **Browser node API**
This list outlines the functionality of various functions used in Browser node in order to access and manipulate web content.\
\
Whenever you see "cssSelector", it means that you will want to use [the standard cssSelector](https://www.w3schools.com/cssref/css_selectors.php) syntax to pass the selector to the function.
You can use "inspect element" on any of webpage elements to find its property.
#### `click`
* **Description**: Performs a click on a web element identified by a CSS selector.
* **Input**:
* `cssSelector`: A CSS selector string for identifying the target element.
* **Output**: None.
**Example usage:**\
\
`click("#username");`
Explanation: clicks on element that has "id="username"" in the source.
`click("[name=bigbutton]");`
Explanation: clicks on element that has "name="bigbutton"" in the source.
#### `findVisibleElements`
* **Description**: Finds visible HTML elements and adds a random string value to the specified attribute. This funciton is included in all existing llm functions, but can be useful if you want to continue working with browser node output, and then re-enter another browser node to work with the page.
* **Input**:
* `elements`: A comma-separated string of HTML element names (div, p, textarea. input etc).
* `attribute`: Any text string, it is used to mark returned elements for future usage in the program. Leave "" if you do not plan to use the output in any of LLM Browser functions.
* selector (optional): return contents of only specific selector
* **Output**: Returns a string containing the HTML of the found elements.
**Example usage:**
`findVisibleElements('div','data-llm-id');`
Explanation: Returns all page elements of type div and adds a random string value as a new attribute called "data-llm-id". The new attribute is only useful if you plan to further use LLM browser functions such as llmClick.\
\
`findVisibleElements('div','llm-data-id', "selector:#resultsTable");`
Explanation: Only returns elements of type div that has id "resultsTable". Uses [cssSelector](https://www.w3schools.com/cssref/css_selectors.php) syntax after the colon (":").
#### `getInnerText`
* **Description**: Retrieves the inner text of an HTML element identified by a CSS selector.
* **Input**:
* `cssSelector`: A CSS selector string for identifying the target element.
* **Output**: Returns the inner text of the found HTML element.
#### `getSecret`
* **Description**: Retrieves a secret value by its name.
* **Input**:
* `secretName`: The name of the secret.
* **Output**: Returns the value of the secret.
#### `getURL`
* **Description**: Retrieves the URL of the currently active browser page.
* **Input**: None.
* **Output**: Returns the current URL as a string.
#### `getValue`
* **Description**: Retrieves a stored value by its name.
* **Input**:
* `valueName`: The name of the value.
* **Output**: Returns the value.
#### `innerHtml`
* **Description**: Captures and stores the inner HTML of an element for later use.
* **Input**:
* `cssSelector`: A CSS selector string for identifying the target element.
* **Output**: None.
#### `isElementPresent`
* **Description**: Checks whether an element is present on the page.
* **Input**:
* `cssSelector`: A CSS selector string for identifying the target element.
* **Output**: Returns a boolean indicating whether the element is present.
#### `llmClick`
* **Description**: Clicks on a web element based on a provided description.
* **Input**:
* `description`: A description of the element to click.
* **Output**: None.
#### `llmClickElement`
* **Description**: Clicks on a web element identified by a description, selecting from a list of elements.
* **Input**:
* `elements`: A comma-separated list of elements.
* `description`: A description of the target element.
* **Output**: None.
#### `llmLogin`
* **Description**: Logs in by entering the username and password into the appropriate form fields.
* **Input**:
* `username`: The username or email.
* `password`: The password.
* **Output**: None.
#### `llmSendKeys`
* **Description**: Sends specified keys to an input element on the page.
* **Input**:
* `description`: A description of the input element.
* `keys`: The string of keys to send.
* **Output**: None.
#### `llmSetValue`
* **Description**: Sets a value in a specified element on the page.
* **Input**:
* `description`: A description of the element.
* `value`: The value to set.
* **Output**: None.
#### `llmSetValueSkipVerify`
* **Description**: Sets a value in a specified element on the page without verifying the action.
* **Input**:
* `description`: A description of the element.
* `value`: The value to set.
* **Output**: None.
#### `llmText`
* **Description**: Finds and retrieves a specified text element on the page.
* **Input**:
* `description`: A description of the text to find.
* **Output**: Returns the text if found.
#### `log`
* **Description**: Logs a message to the server console.
* **Input**:
* `message`: The message to log.
* **Output**: None.
#### `logURL`
* **Description**: Logs the current URL to the server console.
* **Input**: None.
* **Output**: None.
#### `navigate`
* **Description**: Navigates the browser to a specified URL.
* **Input**:
* `url`: The target URL.
* **Output**: None.
#### `navigateStatus`
* **Description**: Navigates to a URL and returns the HTTP status of the page.
* **Input**:
* `url`: The target URL.
* **Output**: Returns the HTTP status code of the page.
#### `outerHtml`
* **Description**: Captures and stores the outer HTML of an element for later use.
* **Input**:
* `cssSelector`: A CSS selector string for identifying the target element.
* **Output**: None.
#### `replaceInnerHtml`
* **Description**: Replaces the content of a web page's element with new HTML content.
* **Input**:
* `cssSelector`: A CSS selector string for identifying the target element.
* `htmlContent`: The new HTML content to replace the current content.
* **Output**: None.
#### `sendKeys`
* **Description**: Sends keys to the browser page.
* **Input**:
* `text`: The text or keys to send. Use newline ("\n") if certain elements require Enter press.
* **Output**: None.
#### `sleep`
* **Description**: Pauses execution for a specified duration.
* **Input**:
* `duration`: The duration to sleep, e.g., "10s".
* **Output**: None.
#### `submit`
* **Description**: Submits a form identified by a CSS selector.
* **Input**:
* `cssSelector`: A CSS selector string for identifying the form.
* **Output**: None.
#### `takeScreenshot`
* **Description**: Takes a screenshot of the current page.
* **Input**:
* `name`: The name to save the screenshot under.
* **Output**: None.
#### `text`
* **Description**: A placeholder function with no defined behavior.
* **Input**: None.
* **Output**: None.
#### `waitFileDownload`
* **Description**: Waits for a file to be downloaded within a specified duration.
* **Input**:
* `duration`: The duration to wait, e.g., "10s".
* **Output**: Returns `true` if the file was downloaded successfully, `false` otherwise.
#### `waitFileDownloadStarted`
* **Description**: Waits for a file download to start within a specified duration.
* **Input**:
* `duration`: The duration to wait, e.g., "10s".
* **Output**: Returns `true` if the download started, `false` otherwise.
#### `waitReady`
* **Description**: Waits for a specified element to be ready on the page.
* **Input**:
* `cssSelector`: A CSS selector string for identifying the target element.
* **Output**: None.
#### `waitVisible`
* **Description**: Waits for a specified element to become visible on the page.
* **Input**:
* `cssSelector`: A CSS selector string for identifying the target element.
* **Output**: None.
***
### Google Search
The **Google Search** node is designed to perform web searches using a search query and retrieve results from Google. This node is helpful for automating search tasks and extracting information from the web. Here's a breakdown of its key settings:
* **Label**: The name of the node, by default labeled **Google Search**. You can change this label to describe your task better.
* **Search Query**: This required field defines what you want to search for. You can specify a query term or phrase that will be used for the search, such as a keyword or question.
* **Site**: This optional field allows you to restrict the search to a specific website. By specifying a site, you can limit the search results to that particular domain, making the search more focused.
* **Limit**: This required field defines the maximum number of search results to return. The minimum value is 1, and in this case, it is set to 10.
* **Fallback Outputs**: This field is for specifying an alternative output or action in case the search doesn't return results or fails to execute.
* **Results**: The search results are displayed here as objects, which can be processed in subsequent steps or workflows.
#### Usage
This node is useful when you need to automate web searches or gather data from specific websites using Google search queries. It can be combined with other nodes for more complex workflows such as data extraction, web scraping, or analysis of search results.
***
### Link Extractor
The **Link Extractor** node is designed to extract URLs from input text or content. This is particularly useful for workflows that involve web scraping, content analysis, or automated URL extraction tasks. Here's a breakdown of its key settings:
* **Label**: The name of the node, by default labeled **Link Extractor**, but you can customize it based on your specific task.
* **Input**: This required field specifies the content from which URLs will be extracted. It can be text, HTML, or any structured content containing URLs.
* **Regex**: You can define a regular expression (regex) pattern here to extract specific types of links or URLs from the input content. This is optional and allows you to filter or narrow down the extraction process.
* **Content Type**: This field specifies the type of content being processed, such as HTML, text, etc., to ensure the node handles the input appropriately.
* **Limit**: This required field defines the maximum number of URLs to extract from the input. The minimum value is 1, and you can set this according to how many links you want to process.
* **Fallback Outputs**: This section allows specifying an alternative action or response if the node fails to extract URLs or doesn't return valid results.
* **URLs (Output)**: The extracted URLs are provided as an output, which can then be used in subsequent nodes or workflows.
#### Usage
This node is ideal when you need to automatically extract URLs from web pages, emails, or any other text content. It can be used in conjunction with web scraping workflows, content mining, or other automation processes.
***
### Readability
The Readability node is used to transform or reformat the content attached to it into a more readable format. Here's an overview of how this node works:
* **Label**: You can customize the label for the node to make it easier to identify within the workflow.
* **Attachment**: This is the input field where you specify the content that you want to convert or format for readability. The attachment can be either:
* **String**: A URL string pointing to the web page whose content you want to extract.
* **File**: A file containing the content to be processed. Supported file types: pdf, htm/html, doc/docx, txt.
* **Format**: This dropdown allows you to choose the format in which the content will be processed. The available formats include:
* **HTML**
* **Markdown**
* **Readability**
* **Plain**
* **Fallback Outputs**: This section allows you to define an alternative action or result in case the main process fails.
***
We’d love to hear from you! Reach out to ****
# API
Configuring Authorization in the Generic API Node
The **Generic API Node** in Integrail’s Agent Studio lets you connect to external APIs and retrieve data as part of your workflow.
### Step 1: Accessing the Generic API Node Settings
1. Open the workflow in Agent Studio where your **Generic API Node** is placed.
2. Select the **Generic API Node** and click on **Settings** to open the configuration panel where headers and authentication details can be added.
***
### Step 2: Common Authorization Methods and Examples
#### **A. Bearer Token (OAuth 2.0)**
Bearer tokens are widely used for secure API access via OAuth 2.0.
* **Use Case:** When the API requires a token-based authorization.
* **Example Configuration:**
* **HTTP Method:** Select the appropriate method (e.g., GET, POST).
* **URL:** Enter the API endpoint, e.g., `https://api.example.com/user/profile`.
* **Settings:**
1. Click on **Settings** at the bottom of the node.
2. Add **String**.
3. Click **Save** on the pop-up.
4. In the new string field, that appeared on the sidebar **Settings** enter:
```makefile
Authorization: Bearer YOUR_ACCESS_TOKEN
```
Replace `YOUR_ACCESS_TOKEN` with your actual token (e.g., `Bearer abcdef1234567890`).
#### **B. Basic Authentication**
Basic Authentication is used for APIs that require a username and password encoded in Base64.
* **Use Case:** When the API requires a username and password for authorization.
* **Example Configuration:**
* **HTTP Method:** Select POST (or as required by the API).
* **URL:** Enter the API endpoint.
* **Encode Credentials:** Combine `username:password` and encode in Base64.
* For example, `user:pass` becomes *`dXNlcjpwYXNz`*.
* **Settings:**
1. Click on **Settings** at the bottom of the node.
2. Add **String**.
3. Click **Save** on the pop-up.
4. In the new string field, that appeared on the sidebar **Settings** enter:
```makefile
Authorization: Bearer YOUR_ACCESS_TOKEN
```
Replace `YOUR_ACCESS_TOKEN` with your actual token (e.g., `Bearer abcdef1234567890`).
#### **C. API Key in Headers**
Some APIs use an API key provided by the service, added to the request headers.
* **Use Case:** When the API requires an API key for access, specified in the headers.
* **Example Configuration:**
* **HTTP Method:** Select GET (or as required).
* **URL:** Enter the API endpoint, e.g., `https://api.example.com/data`.
* **Settings:**
1. Click on **Settings** at the bottom of the node.
2. Add **String**.
3. Click **Save** on the pop-up.
4. In the new string field, that appeared on the sidebar **Settings** enter:
```makefile
Authorization: Bearer YOUR_ACCESS_TOKEN
```
Replace `YOUR_ACCESS_TOKEN` with your actual token (e.g., `Bearer abcdef1234567890`).
#### **D. API Key in URL (Query Parameter)**
Some APIs require the API key as a query parameter in the URL itself.
* **Use Case:** When the API expects the API key as a URL parameter.
* **Example Configuration:**
* **HTTP Method:** Select GET.
* **URL:** Enter the endpoint with the API key as a query parameter, e.g., `https://api.example.com/data?api_key=your_api_key_here`.
***
### Step 3: Adding Additional Headers
Some APIs may require additional headers, such as `Content-Type` and `Accept`.
* **Content-Type:** Specifies the format of data in the request body (e.g., `application/json`).
* **Accept:** Informs the server of the expected response format (e.g., `application/json`).
***
### Summary Table of Common Authorization Methods
| Authorization Type | HTTP Method | URL | Header Key | Header Value |
| -------------------- | ----------- | ---------------------------------- | --------------- | ----------------------------------- |
| Bearer Token | GET/POST | `https://api.example.com/data` | `Authorization` | `Bearer YOUR_ACCESS_TOKEN` |
| Basic Authentication | POST | `https://api.example.com/auth` | `Authorization` | `Basic YOUR_BASE64_CREDENTIALS` |
| API Key (Header) | GET | `https://api.example.com/data` | `x-api-key` | `your_api_key_here` |
| API Key (Query) | GET | `https://api.example.com/data?...` | Query Parameter | Append `?api_key=your_api_key_here` |
***
We’d love to hear from you! Reach out to ****
# Memory Management
In the **Vector Memory Management** interface, you can create, edit, and test your own vector memory sets. Each "Memory Set" contains embedded text data as numerical vectors, which allows for fast and precise searches based on meaning. You can create new memory sets, add memory items, and test your memory search queries. The interface also allows you to manage memory sets dedicated for production or testing purposes, ensuring efficient retrieval of stored data.
### Create a memory set
In the **Create New Memory Set** dialog, you can create a new vector memory set by selecting an embedding provider. This determines how your text data will be converted into vectors for efficient searching. After choosing an embedding provider, you must name the memory set. Once the provider is selected, it cannot be changed later, and the size of the embedding impacts the amount of information that can be encoded. When ready, click "Create New Memory" to generate your new memory set, which will be used for storing and retrieving data based on semantic meaning.
The following embedding providers are available:\
\- OpenAI (Small). Vector size: 1536. Max symbols in Embedded Description field: 28668. \
\- OpenAI (Large). Vector size: 3072. Max symbols in Embedded Description field: 28868.\
\- ThenIper GTE (Large). Vector size: 1024. Max symbols in Embedded Descripton field: 1792.
***
We’d love to hear from you! Reach out to ****
# Benchmark Tool
### Compare Agents and LLMs
In the **Compare Agents and LLMs** screen, you can compare responses from different language models (LLMs) and agents. By simply entering a **System Prompt** to set the behavior of the agent and a **User Prompt** to ask a specific question, you can generate responses across multiple models. This tool allows you to quickly evaluate how various models handle the same input, helping you identify the most appropriate model for your specific use case. It provides insights into response styles, accuracy, and how each model interprets the instructions given in the prompts.
### Create / Edit Benchmarks
Create questions to run against your agents.
### Run Benchmarks
Select question from the dropdown, then models you want to test, and agents to run the benchmark.
### My Benchmarks Results
Review the results:
***
We’d love to hear from you! Reach out to ****
# Integrations
# Google
Gemini + Gmail: your automated workflow duo
Power up your communication game with seamless integration of Gemini and Gmail. Your agents can now:
* Automatically handle and respond to emails with flair
* Sync Gmail data with other platforms to streamline workflows
* Use Gemini to dig deep into data trends and fuel smarter decisions with live insights
***
**Agent inspiration:**
* **Email Assistant**: Automate drafting and organizing Gmail messages.
* **Gmail Inbox Manager**: Fetch and analyze emails, categorize, and respond.
* **Search Automation Agent**: Perform Google searches and retrieve results for research or data analysis.
***
**Nodes Available**:
1. [**Create Gmail Draft Letter**](/agent-studio/editor/web#create-gmail-draft-letter): This node allows agents to draft emails in Gmail. It includes fields for the message, recipient(s), subject, and thread ID. The authentication token is connected to enable seamless interaction with Gmail.
2. [**Get Gmail Letters**:](/agent-studio/editor/web#get-gmail-letters) This node fetches emails from the user’s Gmail account, with options to limit the number of emails, filter by labels (e.g., INBOX), and load attachments.
3. [**Google Search**:](/agent-studio/editor/web#google-search) This node performs Google searches, allowing agents to retrieve search results based on a query, with an optional site filter.
***
These nodes offer vast flexibility, enabling users to build intelligent agents integrated with Google services for automated tasks.
***
We’d love to hear from you! Reach out to ****
# ClickUp
ClickUp, now fully automated
Integrail provides seamless integration with ClickUp, enabling users to automate and streamline their project management workflows through customizable agents.
Tired of manual task updates? Automate the busy work and let your agents handle it all:
* Auto-create and update tasks without lifting a finger.
* Sync ClickUp with other tools to keep everything in harmony.
* Get instant notifications for task and project changes, no sweat.
***
**Agent inspiration**:
* Task automation pro.
* Real-time project update manager.
* Deadline hawk keeping everyone on track.
* Client reporting dynamo.
***
**Nodes Available**:
1. [**Get ClickUp Tasks**](/agent-studio/editor/web#get-clickup-tasks): Automatically retrieve and manage tasks.
2. [**Get ClickUp Teams**](/agent-studio/editor/web#get-clickup-teams): Fetch and manage team details for task coordination.
3. [**Post ClickUp Attachment**](/agent-studio/editor/web#post-clickup-attachment): Attach files to tasks based on specific criteria.
4. [**Post ClickUp Task**](/agent-studio/editor/web#post-clickup-task): Create and manage tasks in ClickUp lists.
***
We’d love to hear from you! Reach out to ****
# Nylas
A developer-first platform for building tailored communication experiences. Seamlessly and securely connect with any email, calendar, or contacts provider through a unified interface.
This solution is designed with developers in mind, making it simple to create custom communication experiences. To get started, you’ll add your account, which will take you to for authorization. There, you’ll log in with your email provider and grant permissions for access.
Once authorized, your account can be used as an Auth Token for any nodes requiring authentication. With just one secure interface, you’ll be ready to connect to email, calendar, and contacts seamlessly.
The [Get Gmail letters](https://help.integrail.ai/agent-studio/editor/web#get-gmail-letters) and [Create Gmail draft letter](https://help.integrail.ai/agent-studio/editor/web#create-gmail-draft-letter) nodes must receive NYLAS authentication through the "Agent Input" node to function properly. This ensures secure access and seamless operation for Gmail-related tasks.
# Telegram
Telegram node: real-time messaging & task automation
With the Telegram node, your agents are ready to automate communication like pros:
* Automate customer interactions with messaging bots
* Trigger real-time notifications for updates or alerts
* Run bots to handle repetitive tasks without missing a beat
***
**Agent inspiration:**
* Instant alert bot for critical updates
* Customer support champion through Telegram messaging
* Survey conductor gathering feedback with automated Telegram polls
***
**Nodes Available**:
[**Fetch Telegram Channel Unread**](/agent-studio/editor/web#fetch-telegram-channel-unread) - This node retrieves unread messages from a specific Telegram channel.
With this integration, users can build sophisticated Telegram bots that automate channel management.
***
We’d love to hear from you! Reach out to ****
# WIX
Wix integration: effortless website automation
When you connect to Wix, managing your website becomes a breeze. Automate it all:
* Seamlessly update content with no manual hassle
* Manage form data and sync with CRMs or other systems
* Keep e-commerce running smoothly with inventory updates and order processing
***
**Agent inspiration**:
* Content publishing pro, always keeping your site fresh
* E-commerce handler, tracking orders and keeping customers in the loop
* SEO optimizer agent, updating your site with the latest keyword trends
***
**Nodes Available**:
[**Create a Wix Blog Post**](/agent-studio/editor/web#create-a-wix-blog-post)
***
We’d love to hear from you! Reach out to ****
# OpenAI
OpenAI node: your all-in-one AI powerhouse
With OpenAI, your agents tap into a treasure trove of AI capabilities across text, image, audio, and code.
**Unlock:**
* Conversational AI, creative writing, and language analysis with GPT-4.
* Stunning images from mere text with DALL-E.
* Lightning-fast code generation and debugging with Codex.
* Audio transcription and processing magic with Whisper.
* Deep image-text linking and classification with CLIP.
* Semantic search and smart clustering with Embeddings.
***
**Agent inspiration:**
* Meeting guru: transcribe, summarize, and generate follow-ups automatically.
* All-in-one content creator: blending text and visuals.
* Full-package producer: delivering complete content kits, end-to-end.
***
We’d love to hear from you! Reach out to ****
# Llama
LLaMA: unleash advanced language mastery
Plugging into LLaMA unlocks your agent's language capabilities, giving them the power to:
* Customize AI-powered language tasks with precision
* Generate and analyze text effortlessly
* Break down language barriers with smooth multi-language translation
***
**Agent inspiration:**
* Content creation machine churning out blogs, ads, and more
* Sentiment analysis expert reading the room, so you don’t have to
* Real-time translation wizard, perfect for global interactions
***
We’d love to hear from you! Reach out to ****
# Microsoft
Microsoft integration: automation across the enterprise
Hook up your agents with Microsoft’s ecosystem and streamline operations across the board:
* Effortlessly manage documents, emails, and collaboration in Microsoft 365.
* Automate team communication and project management in Microsoft Teams.
* Sync data across Microsoft Dynamics for CRM and ERP mastery.
***
**Agent inspiration:**
* Document automation hero for SharePoint file management.
* Task coordinator keeping Microsoft Teams projects humming.
* CRM sync master integrating Dynamics with other platforms.
***
We’d love to hear from you! Reach out to ****
# Google Vertex AI
Vertex AI: AI muscle for multi-agent systems
Integrating Vertex AI brings serious power to your agent network, enabling you to:
* Automate the entire machine learning lifecycle from start to finish.
* Seamlessly tap into Google Cloud services for a smooth AI experience.
* Build and deploy custom models (or let AutoML do the heavy lifting.)
***
**Agent inspiration:**
* Predictive maintenance genius for equipment monitoring.
* Fraud detective spotting anomalies in real time.
* Personalized recommendation wizard curating customer experiences.
***
We’d love to hear from you! Reach out to ****
# Fireworks AI
Unleash AI potential with the Fireworks node
When you add the Fireworks node to your multi-agent lineup, watch your system come alive with cutting-edge AI tools. It empowers you to:
* Build intricate, AI-driven workflows that handle complex challenges.
* Use predictive analytics to drive data-smart decisions.
* Supercharge your operations with AI-powered efficiency boosters.
***
**Nodes Available**:
* A sales forecaster predicting market trends from past data.
* Customer segmentation wizardry powered by AI.
* Workflow optimizer trimming inefficiencies across operations.
***
We’d love to hear from you! Reach out to ****
# Claude
Anthropic models built for endurance, ready for complexity
Crafted for resilience, Anthropic models let you build agents that tackle high-stakes tasks with ease. Picture this:
* Dive into deep, reasoning-driven conversations.
* Design intelligent agents that pick and use tools dynamically, based on real-time needs.
***
**Agent inspiration:**
* A virtual assistant that updates documents and fires off emails.
* A CRM/ERP maestro handling customer data and inventory.
* Smart transcription of images and video for rich insights.
* Code whisperer: generating and debugging on command.
* Multilingual agents breaking language barriers with real-time translation.
***
**Nodes Available**:
* [LLM Chat](https://help.integrail.ai/agent-studio/editor/llm#llm-chat)
* [Caller 2](https://help.integrail.ai/agent-studio/editor/llm#caller-2)
***
We’d love to hear from you! Reach out to ****
# Best Practices
# Website Analysis and Marketing Strategy Agent
Building Custom Agents with Integrail
**Introduction**
This guide showcases an example of a powerful **Website Analysis and Marketing Strategy Agent** built on Integrail. This agent is just one of the many potential agents users can create using the tools and features offered by the Integrail platform. With Integrail, users can design, build, and deploy AI-driven agents without any coding experience, empowering businesses and individuals to automate complex tasks and processes.
#### **How Integrail Empowers Users to Build Custom AI Agents**
Integrail provides a visual, no-code platform where users can create AI-driven agents by linking nodes that perform various functions, such as scraping websites, processing data, and generating strategic outputs. The platform supports the integration of different commands, inputs, and outputs, allowing users to build agents for tasks like:
* Website analysis and strategy generation
* Content summarization
* Process automation
* Data retrieval and analytics
***
### **Node: Agent Inputs**
**Functionality:**
The **Agent Inputs** node serves as the entry point for user interaction with the agent. It collects user-provided data and establishes a session context. Here’s what happens:
1. **User Prompt**:\
The user enters their request or prompt, such as a URL to be analyzed. In our example, the prompt is:\
`"let's analyze https://integrail.ai"`
2. **Session Name**:\
The session name is set to `"data"`, which is critical because the agent will save and retrieve data during this session. As the process flows through subsequent nodes, this session name ensures that all data and context are associated with the correct interaction.
3. **Saved Prompts**:\
Although in this case we are using a live input (i.e., the user provides the URL at the time of use), the system can also use saved prompts if needed. Saved prompts allow for repeated analysis or interactions without requiring the user to re-enter data.
***
### **Node: Caller 2**
This node processes the user’s input and determines if the agent should analyze a website or continue interacting in a conversation.
* **Label**: Caller 2
* **Model**: In this example, we use *gpt-4o-2024-05-13*. However, you can select any other model that fits your specific requirements.
* **User Prompt**:\
`{{inputs.userPrompt}}`\
This input takes the value from the **Agent Inputs** node (in this case, the URL provided by the user).
* **System Prompt**:
```plaintext
plaintextCopy codeYour task is to understand the user's intent and call one of these commands. You MUST respond with a well-formatted JSON of the following format:
{
"name": ,
"inputs":


 2\) Click the "Download" option.
3\) The browser will receive a JSON file and download it.
#### How to import an agent from a JSON file.
1\) Select the agent you want to overwrite in agent selector (dropdown), or make a new agent by pressing the icon to the left of the agent selector, that looks like a page with a "+" sign:
 2\) Click on three vertical dots to the right of agent selector:
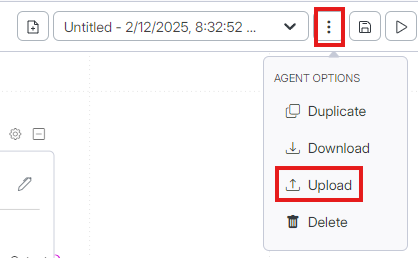 3\) Click the "Upload" option, browse to your file and select "Open".
This will overwrite the agent with the saved confguration.
**Be careful when overwriting existing agent configuration. Importing JSON file will replace already saved agent in this slot.**
# Misc
### My Agents
The "My Agent" node enables you to include another agent within a larger agent workflow, creating modular, reusable systems. The key concept here is encapsulation, where the embedded agent runs independently from the main agent's processes.
This separation ensures that the embedded agent handles its own tasks, logic, and operations without interfering with the flow or state of the broader agent. The outer agent simply interacts with the results, making complex, multi-agent systems manageable and efficient.
### Read CSV
This node accepts input in a form of CSV file. You can specify what delimeter to use.\
It outputs an array of lines from the CSV file, organized in a dictionary, in JSON syntax.
To pass a file as an input, you must use a "file" type agent input, and upload the CSV file.
### Serialize JSON
Serialize and object (such as Google Search output) and return a JSON string.
### Parse JSON
Parse a JSON string and return a list of strings for each element.
# LLM
### Caller 2
The **Caller 2** node is designed to handle commands and responses based on both user and system prompts. Below is a breakdown of its key parameters:
* **Label**: The name given to the node. You can rename this to something meaningful for your workflow.
* **Model**: This allows you to select the language model that will generate responses. You can choose from various models depending on your needs.
* **User Prompt**: This field captures the user’s input (or query) that will be sent to the model for processing. It’s the starting point for generating a dynamic response.
* **System Prompt**: Here, you can set a predefined set of instructions for the model to follow. This can guide the AI on how to behave during the interaction (e.g., responding in a specific tone, or avoiding certain information).
* **Commands**: You can define a list of commands for the node to execute. These commands are triggered based on user inputs or specific conditions within the workflow. Command names must be single words, without spaces.
* **Fallback Outputs**: This field allows you to define a backup or fallback response in case the model call doesn’t return a valid output or fails. It's helpful to maintain flow even in the event of an error.
* **Results**: This section is where the final response generated by the model or command execution is displayed. It's what will be sent back to the user as the output.
This node is typically used when you need to combine user input with system-level commands and provide a response that either calls the model or processes information based on set parameters.
***
### Chart Formatter
The **Chart Formatter** node is designed to convert raw text or uploaded files into a structured data format suitable for chart generation. It leverages a language model to analyze the input and output a JSON object containing `labels` and `datasets`, compatible with common chart libraries.
#### Parameters
* **Label**: The display name of the node. You can rename it to reflect its role in the workflow.
* **Model**: Select the language model (such as GPT-3.5 or GPT-4) used to transform the input into chart-ready JSON. The model interprets the input based on a predefined system prompt.
* **Input**: This is the content to be transformed. You can provide either plain text or a file (CSV, JSON, or TXT).
* CSV files will be automatically parsed into structured objects.
* JSON and TXT files are used as-is after validation.
#### Usage
This node is designed to work **as a preparatory step** before chart rendering. Its output is fully compatible with the **Chart Generator** node, which can take this JSON and create visual representations (e.g., bar, line, pie charts).
***
### Chart Generator
The **Chart Generator** node creates high-quality chart images (PNG or SVG) based on structured JSON input. It supports common chart types like bar, line, pie, and doughnut, and automatically styles the output with colors and labeled legends for clarity.
#### Parameters
* **Label**: The name of the node. You can rename it to describe the specific chart it generates.
* **Chart Data (JSON)**: Required. A JSON string that defines `labels` and `datasets`, matching the structure:
* {"labels": \["Label1", "Label2"], "datasets": \[{"label": "Dataset name", "data": \[100, 200]}]}
* **Chart Type**: Choose between bar, line, pie, or doughnut charts.
* **Format**: Choose whether the output should be in **PNG** or **SVG** format.
* **Make Permanent?**: If enabled, the generated chart image will be stored permanently in your account’s file storage.
#### Usage
This node is typically used **after** a data formatting step, such as the `Chart Formatter` node, which prepares raw input into the expected JSON structure.\
Once valid data is available, the Chart Generator transforms it into a visual chart for reporting, dashboards, or export.
***
### Get Chat History
The **Get Chat History** node is used to retrieve past messages from the conversation history. This node is essential when you need to maintain context or reference previous interactions within a workflow. Here's a breakdown of the key elements:
* **Label**: The name of the node. You can rename this to make it more descriptive based on the specific use case.
* **Limit**: This field determines the number of past messages you want to retrieve. Setting a limit helps to control how many messages are brought back into the current workflow context. The minimum limit is 1, meaning it will retrieve at least one message if available.
* **Messages (object\[])**: This is an output object that contains the retrieved chat history, which can be used by other nodes or functions within the workflow. The output will be in the form of an array of messages.
* **Fallback Outputs**: This field allows you to define an alternative or backup action in case no valid chat history is found or if the retrieval fails. This ensures the workflow can continue even if there's an issue with retrieving the chat history.
* **Results**: The actual output from retrieving the chat history will appear here. It can then be passed to other nodes or used for further processing.
#### Usage
This node is typically used when you need to retrieve past messages to inform future actions or responses. For example, it might be used to maintain conversation context or pull relevant details from earlier in the chat to improve response accuracy.
***
### LLM
The **LLM** node is a streamlined way to interact with a language model (like GPT-3.5) to generate responses based on user input. This node simplifies the configuration process while still offering control over essential parameters. Here’s how each component functions:
* **Label**: The name of the node. By default, it's labeled **LLM**. You can rename it to something more specific based on your workflow.
* **Model**: Choose model from the drop down.
Pricing details for input and output are also provided to help you manage costs based on usage.
* **User Prompt**: This is a required field where you input the user's question or message that the model will process to generate a response.
* **System Prompt**: This optional field allows you to set instructions or guidelines that define how the model should behave while responding. For example, you can instruct the model to respond formally or focus on a specific topic.
* **Temperature**: This parameter controls the randomness or creativity of the model's responses. A higher value (closer to 2) produces more diverse and creative answers, while a lower value (closer to 0) makes the output more deterministic and focused.
* **Presence Penalty**: This setting discourages the model from repeating the same content, ensuring more varied responses. Higher values encourage the model to avoid repetition and generate new content.
* **Max Tokens**: This field sets the maximum number of tokens (words or parts of words) the model can use to generate a response. Limiting this helps control the length of the generated text.
* **Top P**: This is a sampling method that controls how broad the model’s responses can be. A lower value restricts the model to consider only the most likely tokens, while a higher value allows more creative and varied responses.
#### Usage
The **LLM** node is ideal for straightforward text generation where you need quick, efficient interactions without a lot of complex settings. It's a simplified interface that still gives you control over key parameters like temperature, token length, and response variability. This makes it perfect for scenarios where simplicity and speed are more important than fine-tuning.
***
We’d love to hear from you! Reach out to **


